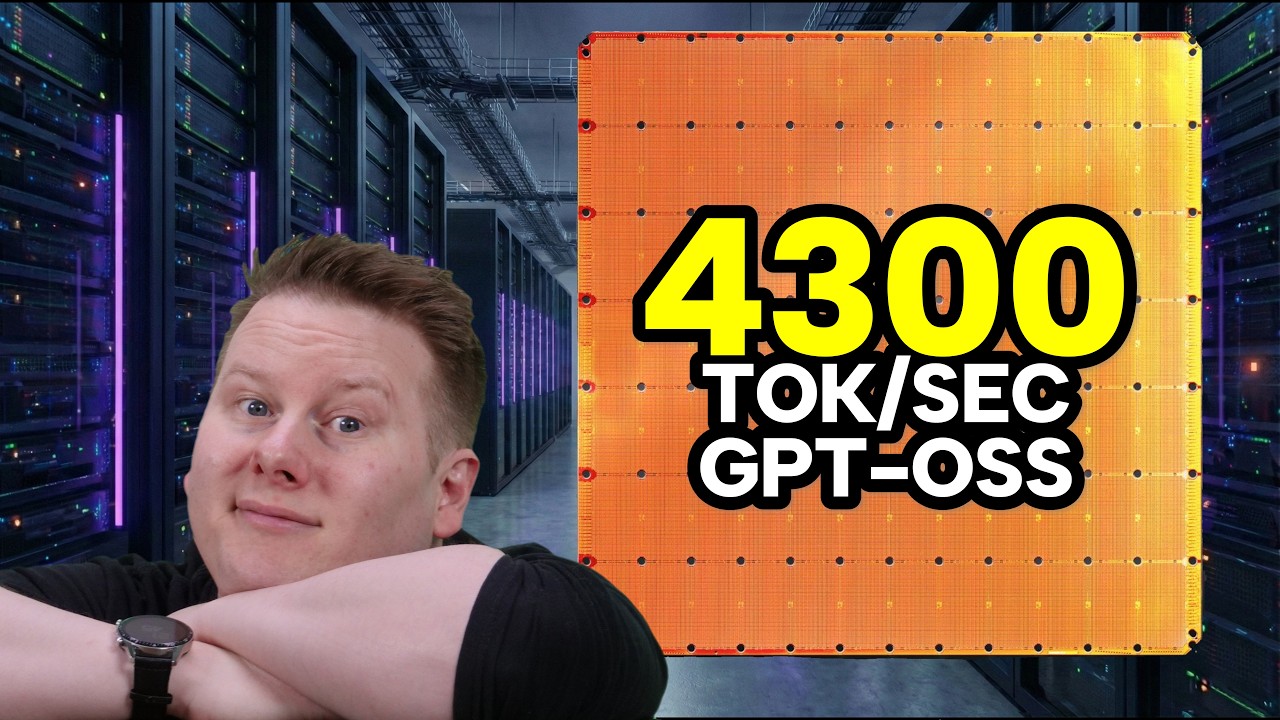
The video discusses the evolution and advancements of Cerebras’ wafer scale engine (WSE) chips, which are among the largest and most powerful AI compute engines available. Cerebras has pioneered the concept of wafer-scale integration, building massive chips as large as a dinner plate by stitching together numerous cores on a single silicon wafer. This approach allows for extremely high compute density and memory bandwidth, enabling fast machine learning inference and training by keeping all data and weights on-chip. The company has partnered with TSMC to achieve near-perfect physical yield despite manufacturing defects, using smart routing to bypass faulty cores.
The latest generation, the WSE 3.5, is a turbocharged version of the previous WSE 3, offering roughly double the frequency and performance, with up to 250 petaflops of sparse FP16 compute. This chip maintains the same 900,000 cores and 44 GB of SRAM but significantly improves memory bandwidth and networking capabilities. A key innovation is the modular “backpack” design that allows three WSE chips to be housed in a single rack, each with enhanced liquid cooling and modular networking interfaces supporting up to 2.4 terabits per second. This design enables scalability for large AI models, supporting trillions of parameters with improved chip-to-chip latency.
Cerebras’ new CS4 system, which incorporates these chips, is optimized for automated manufacturing and deployment at scale, reducing component counts and simplifying assembly compared to earlier generations. This efficiency addresses concerns about supply and production capacity, allowing Cerebras to meet growing demand, including a major partnership with OpenAI. The CS4 rack consumes about 120 kW of power for three chips, comparable to other high-end AI hardware like Nvidia’s NVL72, but delivers significantly higher token processing speeds, doubling throughput compared to the previous generation.
The video also touches on the broader AI hardware ecosystem, noting Cerebras’ collaborations with AMD and AWS, and its compatibility with Nvidia systems. It contrasts Cerebras’ approach with other specialized AI chips like Groq and Talis, emphasizing Cerebras’ versatility in running a wide range of transformer models at high speed. The company aims to support increasingly large models, up to 10 trillion parameters, by the end of the decade, focusing on speed as a critical competitive advantage in AI inference workloads.
In conclusion, Cerebras continues to lead in ultra-fast AI compute hardware with its wafer-scale engines and innovative system designs. The new generation CS4 system represents a significant step forward in performance, scalability, and manufacturability. The video invites viewers to share their thoughts and questions about Cerebras’ technology and future developments, highlighting the company’s commitment to evolving its platform to meet the demands of next-generation AI models and workloads.