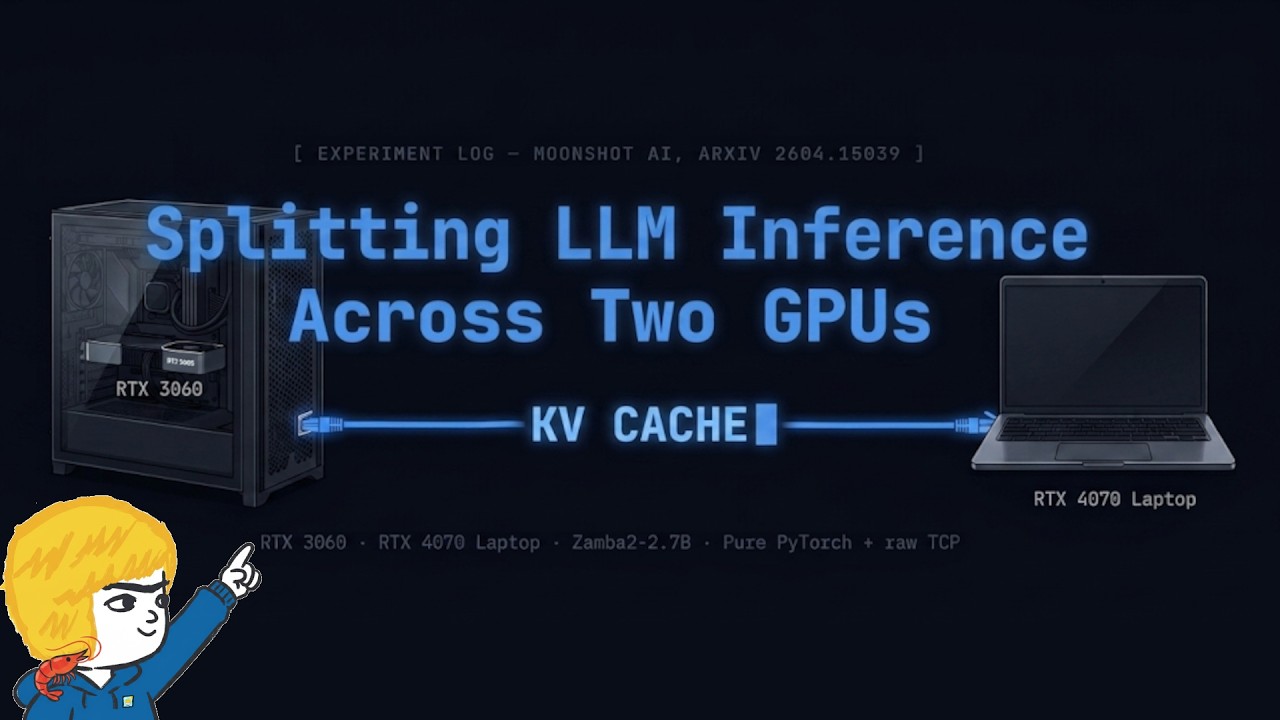
The video explains how to split large language model inference across two GPUs by managing the prefill, decode stages, and KV cache synchronization to optimize performance and reduce latency. It highlights the importance of balancing computational load, handling full attention layers, and addressing networking bandwidth challenges to enable efficient multi-GPU processing for larger models and longer sequences.
The video explores the process of splitting large language model (LLM) inference across two GPUs, focusing on the stages of prefill, decode, and KV cache management. The presenter discusses the technical challenges and solutions involved in distributing the workload efficiently to leverage the combined computational power of multiple GPUs. This approach aims to optimize performance and reduce latency during model inference, which is critical for real-time applications.
A key aspect highlighted is the handling of the KV cache, which stores key and value tensors used during the attention mechanism in transformer models. Proper management and synchronization of the KV cache across GPUs are essential to maintain consistency and accuracy in the generated outputs. The video explains how the KV cache is split and shared between GPUs to ensure seamless continuation of the decoding process without redundant computations.
The presenter also addresses the importance of full attention layers in the model architecture, emphasizing their role in capturing complex dependencies within the input data. By distributing these layers across GPUs, the system can process larger models or longer sequences than would be possible on a single GPU. This distribution requires careful coordination to balance the computational load and minimize communication overhead between devices.
Networking considerations are discussed, particularly the impact of Ethernet bandwidth on data transfer speeds between GPUs. The video clarifies that the bandwidth is measured in gigabits per second, not gigabytes, which affects the throughput and latency of inter-GPU communication. Efficient data transfer protocols and hardware configurations are necessary to prevent bottlenecks that could negate the benefits of parallel processing.
Throughout the video, references are made to specific tools and platforms, such as Kimi.ai and Zyphra, which facilitate the implementation of multi-GPU inference strategies. The presenter also mentions H20s as part of the ecosystem supporting advanced machine learning workflows. Overall, the video provides a comprehensive overview of the technical considerations and practical steps involved in splitting LLM inference across two GPUs to enhance performance and scalability.