The creator discusses new research showing that images can encode information more efficiently than text for AI models, potentially reducing token usage and costs, but experiments reveal that models currently process image inputs slower and less effectively than text. While promising, the creator advises cautious experimentation and optimization before fully adopting image-based inputs, as current AI systems are primarily optimized for text.
The video begins with the creator expressing satisfaction at being proven right about a recent discovery: images might be more efficient than text for AI models. Despite initial skepticism and criticism from others, new research from DeepSeek supports this claim, showing that a single image token can represent the equivalent of ten text tokens with near-perfect accuracy. This suggests that models process images more efficiently, potentially reducing costs and token usage significantly, which could be beneficial for users facing prompt length limits in text-based AI systems.
The creator explains the technical reasoning behind why images might be more efficient than text. Text tokens are discrete and limited in variety, each representing a fixed embedding, whereas image tokens are continuous and can represent a vast range of variations within the embedding space. This continuous nature allows image tokens to encode much more information per token compared to text tokens, which are comparatively inefficient for AI models despite being effective for human communication. The analogy to human brain processing is mentioned but treated cautiously, as the exact workings of the brain remain unclear.
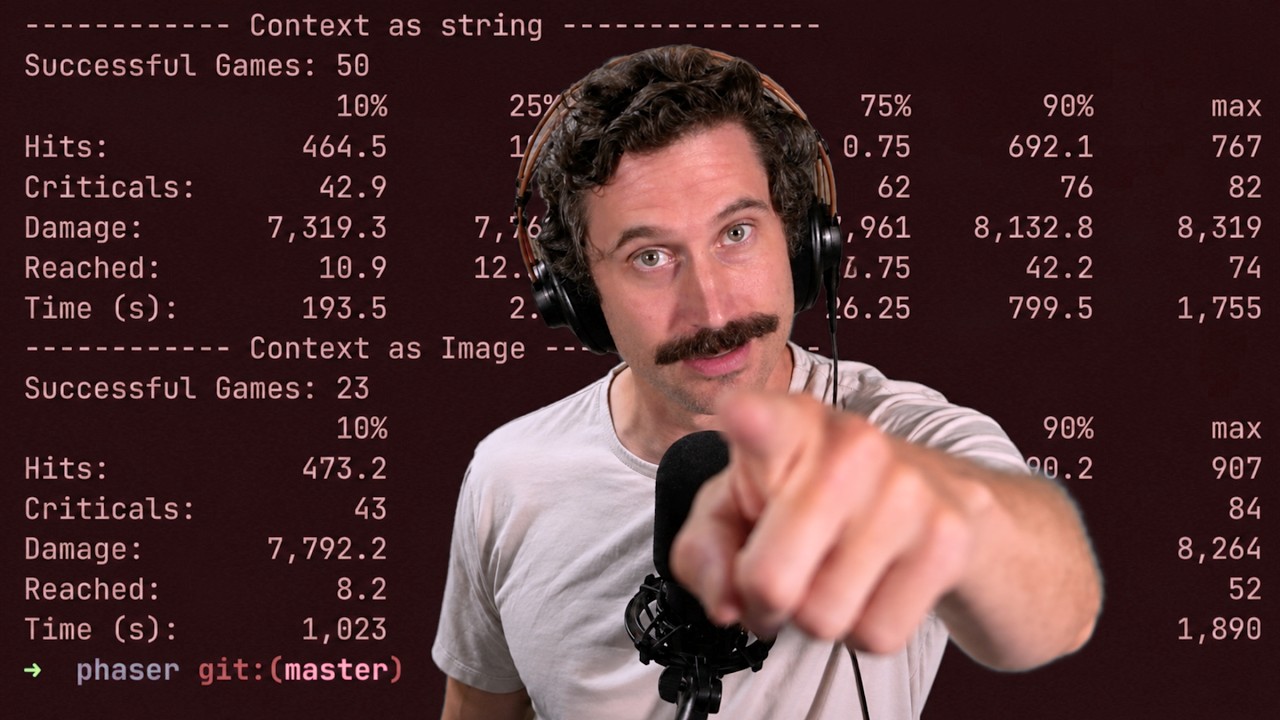
To test this theory, the creator conducted experiments using a tower defense game controlled by AI models. They compared performance using the game’s context provided as text versus as an image. The text-based context resulted in more successful and faster game completions, while the image-based context led to fewer successes and much longer game times, although the damage dealt was somewhat higher. This suggests that while images may encode more information, the models currently take longer to interpret and act on that information effectively.
The token usage statistics from the experiments further highlight the trade-offs. The image context used significantly fewer tokens overall, supporting the idea of efficiency in token consumption. However, the increased complexity and slower processing time with images indicate that this approach is not yet straightforward or universally better. The creator emphasizes that extensive experimentation and optimization are necessary before fully adopting image-based inputs for AI models, especially since many current AI systems are primarily designed around text inputs.
In conclusion, the creator advises caution against rushing to convert all AI inputs to images based on hype alone. While there is promising potential for images to improve efficiency and reduce costs, the technology and workflows are still evolving. Users should experiment and evaluate what works best for their specific use cases. The video ends with a reminder that many AI tools are optimized for text, and future improvements may unlock even greater benefits for image-based inputs as the technology matures.