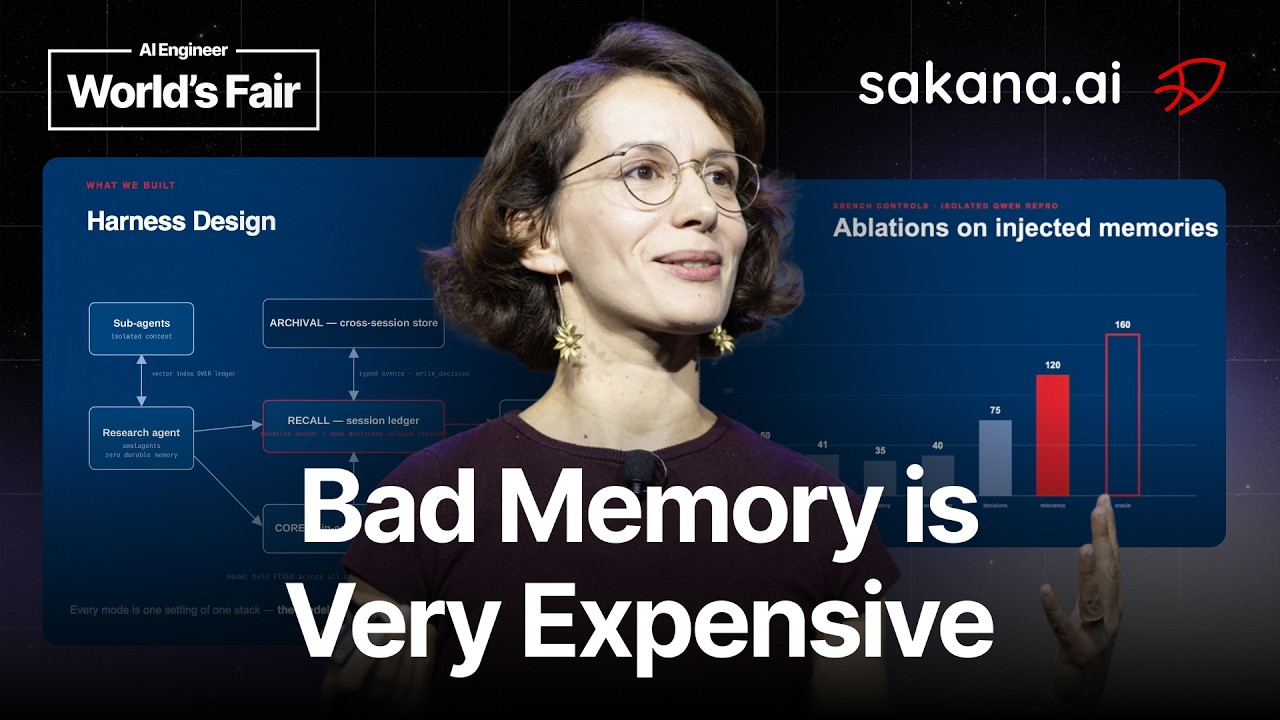
Stefania Druga, a research scientist at Sakana AI in Tokyo, presents on the topic of memory harnesses for long-running research agents operating on local devices. She highlights a common challenge in long-horizon tasks known as “context blow,” where models forget previous information, contradict themselves, or lose track of the task. This issue is becoming increasingly important as tasks grow longer and model releases become less frequent, necessitating effective memory management strategies to maintain performance over extended interactions.
Druga emphasizes the growing relevance of local models, citing recent industry trends such as Coinbase’s shift to local models to reduce AI costs while increasing usage. She demonstrates her experimental setup using a powerful Mac with M3 Ultra hardware, running two quantized models: Qwen 27B and Deep Seek V4 Flash. Her approach to memory is conceptualized as a write-manage-read control loop, where memory is not just stored but actively managed to support the agent’s reasoning over time.
Her memory harness design involves a layered recall system tested across different modes: no memory, vector-based retrieval (RAG), a decision ledger that tracks and prioritizes past decisions, and an oracle providing ground truth memory. Through experiments, she finds that for tasks where all relevant information fits within the model’s context window, memory harnesses add little benefit and only increase computational cost. However, for long-horizon tasks where relevant information exceeds the context window, a well-structured memory harness significantly improves performance.
Using benchmarks like X-Bench and Spider V2, Druga shows that the ranked decision ledger recall policy outperforms other methods, including simple gating or vector retrieval. Interestingly, even the oracle, which supplies the correct memory, does not guarantee perfect results because the model may still ignore or misinterpret the retrieved information. Her findings suggest that a carefully designed recall policy is crucial for both improving accuracy and reducing computational expense, as poor memory management can waste tokens and mislead the agent.
In conclusion, Druga advocates for treating recall policy as a critical metric in AI system design and encourages further exploration of memory techniques, which range from simple file retrieval to complex memory models. She underscores the value of running these experiments on local models for full control and sovereignty over data and computation. Finally, she highlights Sakana AI’s commitment to sovereign AI development in Japan and invites interested researchers to join their team.