Ronak Malde, founder of Trajectory, discusses the challenges and advancements in scaling up continual learning for AI systems. He begins by highlighting the current state of AI progress, where benchmarks have rapidly saturated, making further improvements increasingly time-consuming and expensive. Despite massive investments in scaling reinforcement learning (RL) environments, many benchmarks do not reflect real-world use cases. Malde emphasizes the importance of continual learning, where models continuously update based on real-world data and interactions, mirroring how humans learn.
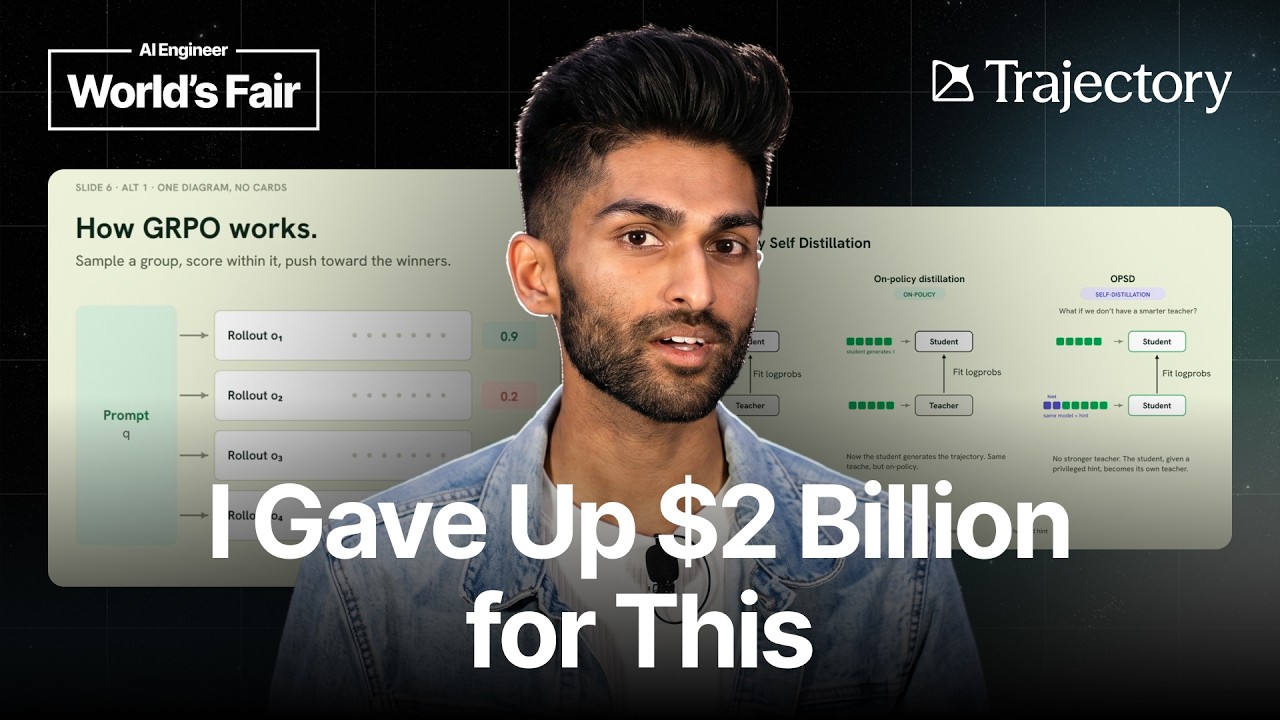
Malde reviews the evolution of training algorithms, from supervised fine-tuning (SFT) to reinforcement learning with human feedback (RLHF), and finally to on-policy methods like GRPO. While GRPO improved on-policy sampling and reduced catastrophic forgetting, it still suffers from issues such as task distribution mismatches, heavy infrastructure demands due to parallel rollouts, and reliance on sequence-level rewards rather than token-level feedback. These limitations motivate the search for better continual learning algorithms that can operate efficiently and effectively in real-world settings.
He introduces a novel algorithm called On-Policy Self-Distillation (OPSD), which leverages a teacher-student model framework but innovates by using on-policy rollouts from the student model itself rather than fixed offline datasets. The key insight is to provide the teacher model with privileged information or hints that make it “smarter,” allowing the student to learn from a more informed teacher. This approach eliminates the need for parallel rollouts, enables token-level reward signals, and better aligns training with real-world online task distributions, resulting in improved performance on short-horizon tasks like chatbots.
However, scaling OPSD to larger models and longer tasks reveals new challenges, such as the “buttweight problem,” where the model gets stuck in suboptimal local distributions, and “hint leakage,” where the student model shortcuts reasoning by exploiting privileged hints. Malde discusses solutions including step-level divergence weighting to manage distribution shifts during long trajectories and residual guidance to control the influence of hints, preventing the model from overfitting to privileged information. These innovations have allowed Trajectory to scale OPSD to 12-billion parameter models handling complex multi-step tool calls, surpassing traditional RL methods.
Finally, Malde shares Trajectory’s vision of building a platform that continuously improves AI models by turning every user interaction into a learning opportunity, creating smarter software over time. The platform integrates agent trace data from production environments, optimizes it in a self-supervised loop, and deploys continually learning systems with a control plane overseeing the process. While acknowledging that true real-time continual learning remains an open challenge, Trajectory is actively addressing both algorithmic and infrastructure hurdles. The talk concludes with a Q&A emphasizing the exciting, largely unexplored potential of continual learning to transform AI in the coming years.