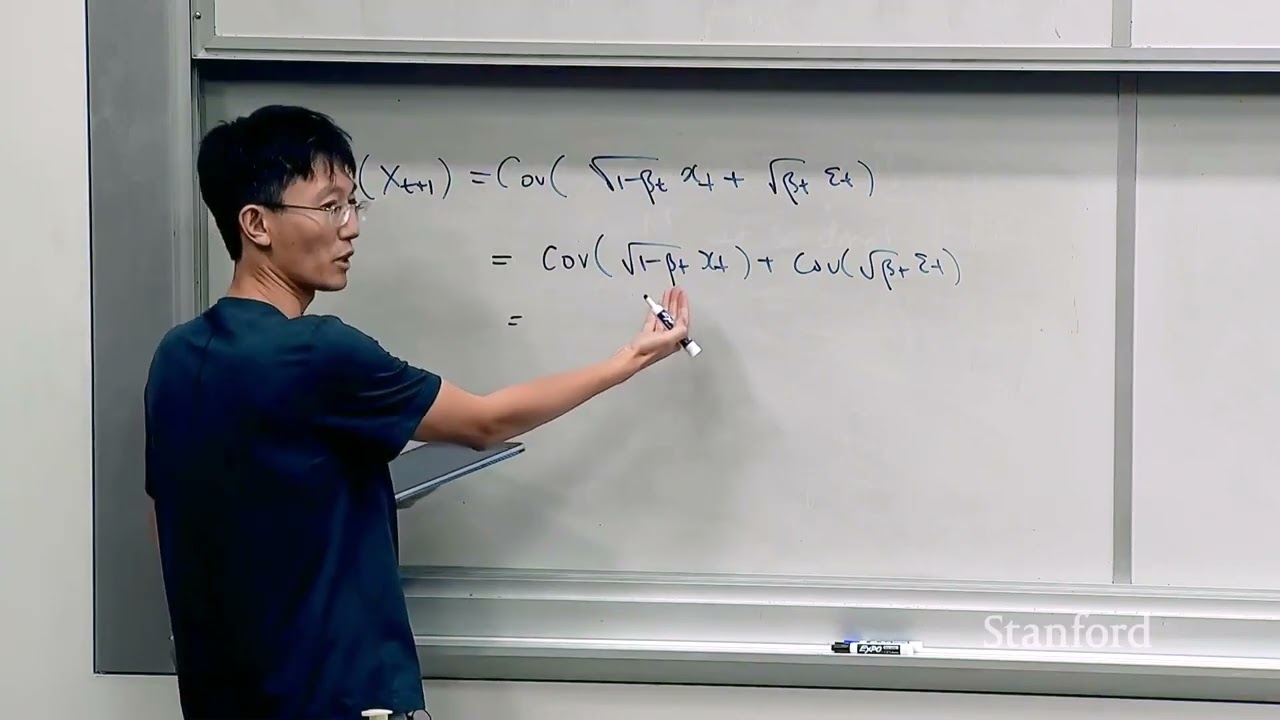The lecture introduces diffusion models as a powerful class of generative models primarily used for image generation, with applications extending to video, robotics, and even language modeling. Unlike traditional generative models such as GANs and variational autoencoders, diffusion models have become the predominant approach due to their superior performance. The core task is to generate realistic images that resemble the distribution of a given dataset by learning a model that can reverse a noising process applied to clean images. This noising process gradually adds Gaussian noise to images over many steps, transforming them into pure noise, and the diffusion model learns to reverse this process step-by-step to recover clean images from noise.
The forward noising process is mathematically defined by iteratively adding small amounts of Gaussian noise to the image, controlled by parameters beta_t, which are typically small scalars. This process maintains the overall scale and covariance structure of the data, gradually transforming the original image distribution into a standard normal distribution as the number of steps increases. The lecture explains the mathematical formulation of this process, including how the noisy image at any step can be expressed as a linear combination of the original image and Gaussian noise, with coefficients that depend on the product of (1 - beta_t) terms. This forward process is fixed and known, requiring no learning.
The reverse process, which the model aims to learn, involves estimating the conditional distribution of a less noisy image given a noisier one. This reverse process is parameterized as a Markov chain of Gaussian transitions, where the mean is predicted by a neural network and the variance is either fixed or learned. The lecture discusses why the reverse transitions are also Gaussian, citing deep theoretical results from stochastic process theory, and explains that the reverse process inherently involves uncertainty, as multiple noisy trajectories can lead to the same noisy image. The continuous-time perspective of diffusion processes is briefly introduced, highlighting the connection to Brownian motion and the mathematical foundations for the Gaussian nature of the reverse process.
Training diffusion models is framed as a maximum likelihood problem with latent variables, where the evidence lower bound (ELBO) is used to optimize the model parameters. The forward noising process defines a posterior distribution Q over noisy images given the clean image, while the model defines a prior distribution P over the reverse process. The ELBO decomposes into reconstruction terms and KL divergences between these distributions. By leveraging the Markov property and known Gaussian forms of the forward process, the KL divergences can be decomposed into sums over individual time steps, each involving KL divergences between Gaussian distributions. This decomposition simplifies the training objective to minimizing the difference between the predicted reverse mean and the true posterior mean at each step.
Finally, the lecture clarifies notation and conceptual points, emphasizing that the forward noising process Q is fixed and known, while the reverse process P_theta is learned. The loss function reduces to a sum of KL divergences between Gaussian distributions with known variances and means predicted by the model, which can be efficiently computed. The lecture also addresses common confusions about the Gaussian assumptions, the role of noise in the reverse process, and the benefits of gradual denoising over one-shot generation. The mathematical rigor is balanced with intuitive explanations, and the lecture concludes by setting the stage for further details on training and optimization in subsequent sessions.