The video titled “The Right Harness is All You Need” details the creator’s extensive journey experimenting with PCIe Gen 5 switches to optimize GPU performance, particularly with RTX Pro 6000 cards. The creator faced numerous challenges, including compatibility issues with older motherboards lacking resizable BAR and above 4G decoding features, which are essential for stable multi-GPU setups. Despite trying various machines like the Dell T2 tower, Puget, and Box workstations, only one machine on the premises could run the PCIe switch at full speed. The video provides an in-depth explanation of the physical setup, including the rettimer, MCIO cables, and GPU adapters, emphasizing the importance of proper configuration and cooling.
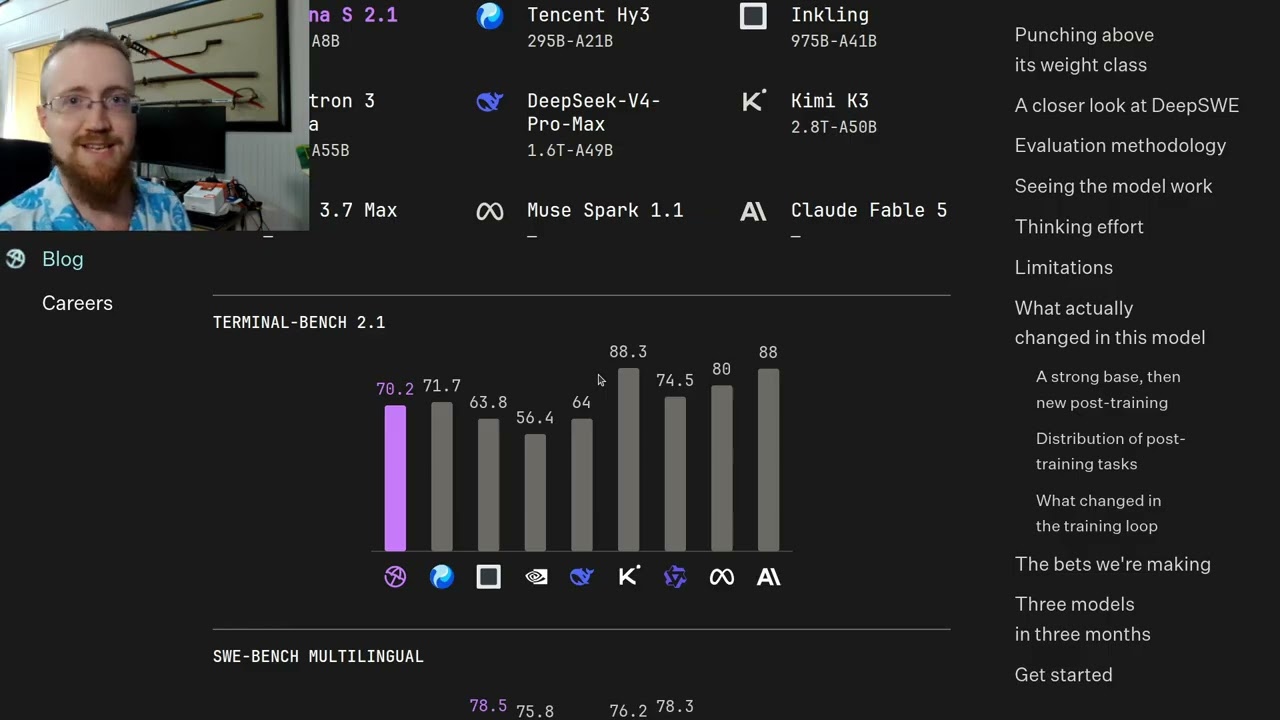
The creator also discusses recent developments in AI model benchmarking, focusing on models like Poolside Laguna S21, Thinking Machines’ small model, and Deepseek V4 Flash 0731. While Poolside Laguna boasts impressive benchmark scores with 118 billion parameters, the creator was unable to validate these results, suspecting overfitting to their specific benchmarking harness. Deepseek V4 Flash 0731, despite hype, initially performed poorly on the creator’s minimalistic Minion coding agent harness, but when run with the more complex OM harness, its performance dramatically improved, highlighting how the choice of harness significantly impacts model evaluation.
The OM harness emerged as a critical factor in unlocking the full potential of certain AI models, especially Deepseek V4 Flash 0731. While GLM52 models showed only modest improvements with OM, Deepseek’s model saw a substantial jump in task completion rates, from 44 to 64 out of 89 tasks. However, this improvement comes at the cost of increased token usage and longer time to solution due to OM’s iterative approach. The creator notes that while OM is slower, it iterates until a valid solution is found, which can be advantageous for complex problems but may not always justify the extra computational expense.
Benchmarking results revealed that GLM52 3.25 bits per weight with the OM harness currently holds the top spot in performance, completing 73% of tasks successfully. Deepseek V4 Flash 0731 with OM closely follows, demonstrating that harness choice can rival or surpass model architecture improvements. The creator also mentions upcoming models like Quen 38 Max with vision capabilities, which are expected to enhance tasks involving visual inputs, such as robotics and web design. The video underscores the importance of vision-enabled models for practical applications requiring image understanding.
Finally, the creator shares personal reflections on hardware setups, praising the Dell T2 tower for its compact size and quiet operation, and expressing frustration with older workstations’ BIOS limitations. They emphasize the convenience of modular setups where the GPU rack and switch can be moved between machines easily. The video concludes with a glimpse into ongoing robotics projects using the G1 model and hints at future content exploring AI training and robotics applications, inviting viewers to engage with questions and suggestions.