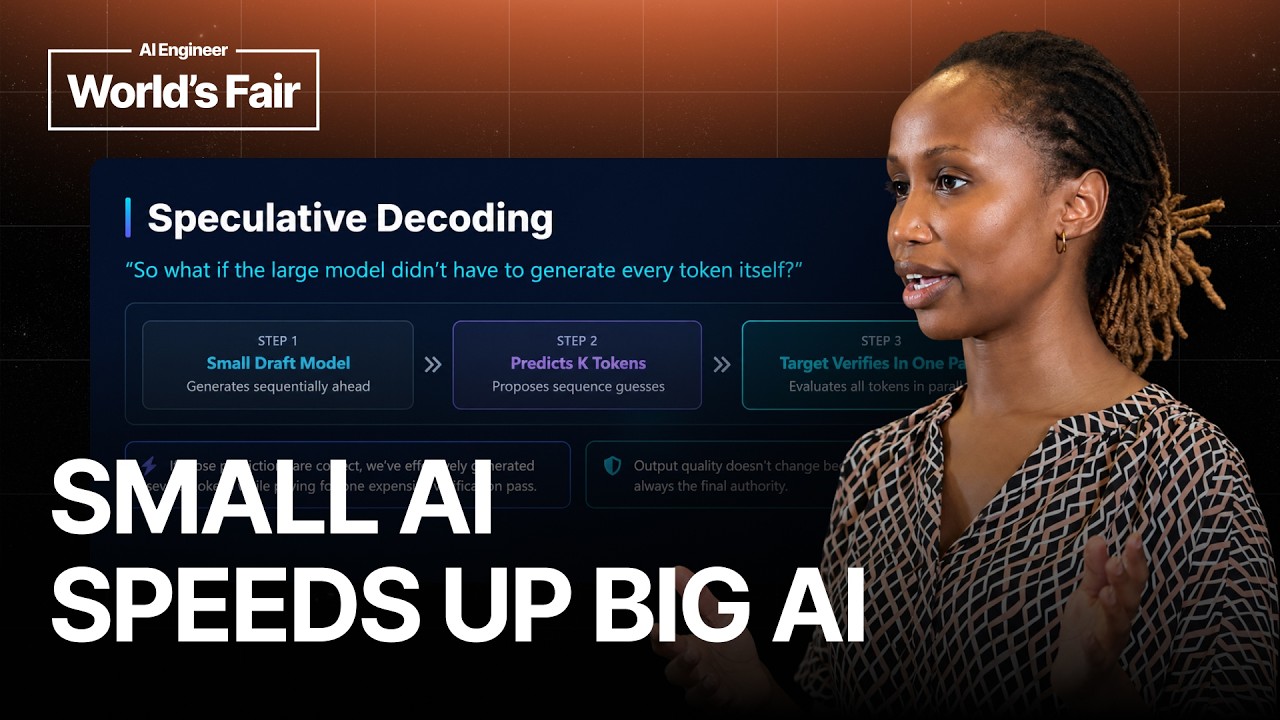
In this presentation, Sheilah, a Developer Advocate at Akamai, discusses the concept of speculative decoding and how to determine if it is beneficial for specific workloads. She begins by explaining the typical process of large language models (LLMs) handling a query, which involves two phases: building a KV cache from the input tokens and then decoding to generate the output tokens sequentially. This decoding phase can be computationally expensive and slow, especially for large models like LLaMA 70B, which require many forward passes, leading to high latency in applications.
Speculative decoding aims to reduce this latency by using a smaller, faster draft model to predict several tokens ahead, which the larger target model then verifies in a single forward pass. If the target model rejects any tokens, it recomputes them. This approach can speed up token generation and reduce inference costs, but it requires hosting two models simultaneously, which increases memory usage due to the need for separate KV caches. Therefore, speculative decoding is most advantageous when there is extra GPU capacity available, such as in low concurrency scenarios.
Choosing the right draft model is critical for the success of speculative decoding. The draft model should be significantly smaller—typically 10 to 50 times smaller—than the target model, share the same tokenizer, and ideally come from the same model family to avoid token translation issues. The draft model must also balance speed and accuracy to ensure a high acceptance rate of tokens by the target model. Sheilah shares her experience running speculative decoding on an NVIDIA Blackwell GPU, where she selected a small draft model to fit alongside the larger target model within the GPU memory constraints.
Sheilah highlights that speculative decoding is more effective for structured tasks such as coding, generating JSON, or SQL queries, where token predictions are more predictable and the acceptance rate is higher. In contrast, creative tasks like poetry or brainstorming, which involve more variability and higher temperature settings, tend to have lower acceptance rates, reducing the benefits of speculative decoding. Additionally, speculative decoding accelerates only the token generation phase and not the initial context processing, so workloads with very long input contexts may see less improvement.
Finally, Sheilah recommends using vLLM, a serving engine with good documentation, for implementing speculative decoding and points to resources such as blogs and research papers for deeper understanding. She encourages viewers to explore Akamai’s GitHub and Discord channels for more information and community support. She also expresses interest in creating more content to help others learn about speculative decoding and inference optimization techniques.
Useful Links
- vLLM documentation — Directly explains and enables implementation of speculative decoding as discussed in the video.
- Akamai developers GitHub repository — Contains source code and resources related to speculative decoding and inference optimization presented in the video.