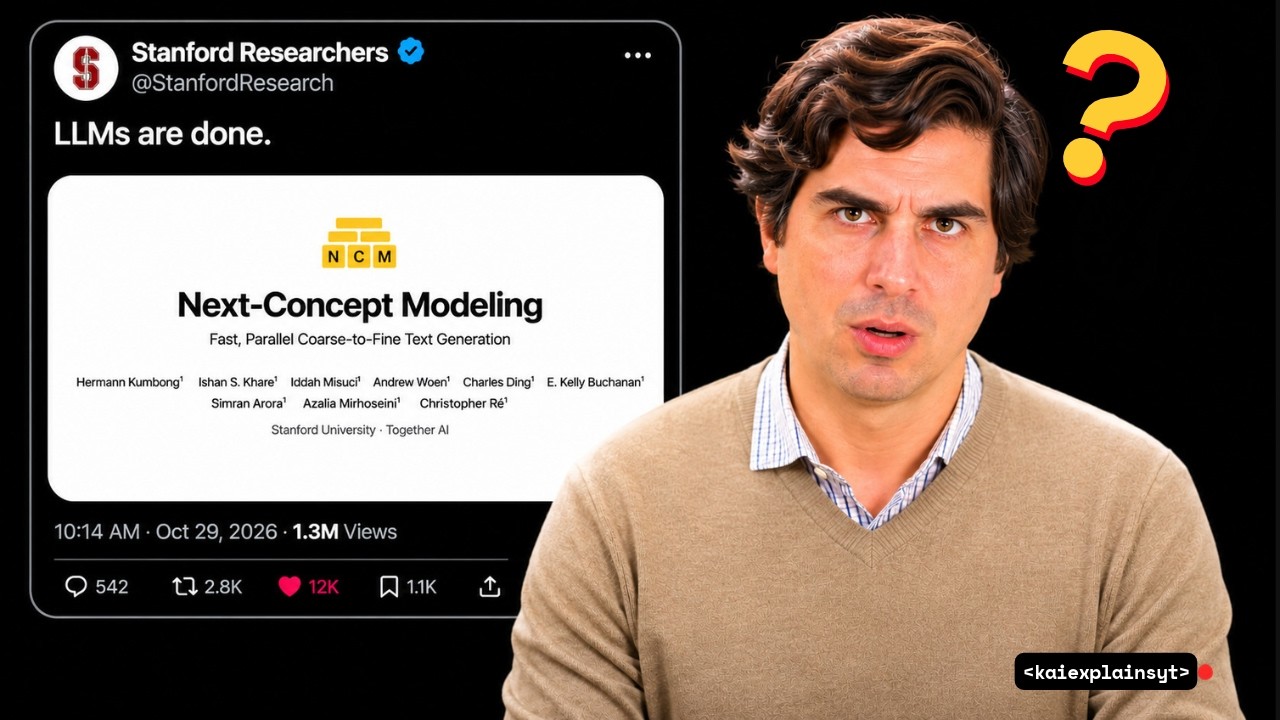
The video explains that while Stanford and Together AI’s Next Concept Modeling (NCM) technique reduces the number of passes needed for text generation, it primarily optimizes memory bandwidth without addressing the larger memory capacity demands of holding long conversation histories in AI systems. Consequently, despite its clever approach and potential speedups for certain tasks, NCM is unlikely to render NVIDIA’s high bandwidth memory chips obsolete or disrupt large-scale AI infrastructure in the near future.
The video discusses the hype and reality surrounding a new AI research paper from Stanford and Together AI called Next Concept Modeling (NCM), which claims to drastically reduce the number of passes needed to generate text from 1,024 to just 32. This sparked sensational headlines suggesting that NVIDIA’s expensive high bandwidth memory (HBM) chips could become obsolete. The presenter, however, cautions viewers to look beyond the headlines and understand the technical nuances before jumping to conclusions about a potential industry upheaval.
NCM introduces a novel approach to text generation by writing in layers, starting with a coarse sketch and progressively adding detail, similar to how an artist works. This allows the model to generate many tokens in parallel rather than sequentially, which is particularly effective for tasks like solving Sudoku puzzles where all parts depend on each other simultaneously. While this architecture is clever and shows promise in specific domains, it has not yet been proven to outperform standard language models on general text tasks or at large scales typical of models like GPT or Claude.
A critical distinction the video makes is between two roles of memory in AI chips: feeding (bandwidth) and holding (capacity). NCM optimizes bandwidth by reducing the number of passes needed to read model weights, but it does not reduce the memory capacity required to hold large conversation histories (KV cache), which dominate memory usage in modern AI systems. Since most memory in AI servers is used to store these long conversations rather than repeatedly reading model weights, NCM’s improvements address only a small part of the overall memory bottleneck.
The video also highlights real-world usage data showing that cached tokens (memory) make up about 90% of the tokens processed by AI agents, with only about 1% being new output generated by the model. This means that while NCM speeds up the writing process, it does not reduce the massive memory demands of holding and managing long conversations and context. Additionally, NCM’s compression method is lossy and struggles with structured data formats common in AI agent outputs, which could limit its practical utility in real applications.
Finally, the presenter explains that while NCM could offer significant speedups for local, single-user GPU inference where bandwidth is a bottleneck, it is unlikely to disrupt large-scale AI infrastructure or eliminate the need for NVIDIA’s HBM memory chips anytime soon. The supply chains and contracts for memory production operate on long timelines, and NVIDIA continues to invest in advanced memory technologies. The video concludes by urging viewers to critically evaluate future AI breakthroughs by considering whether they improve writing speed or reduce memory capacity, as the latter is the more pressing challenge in today’s AI systems.