Mistral Large 4 is a groundbreaking language model boasting 1 trillion parameters with open weights available for download as of October 29th. Unlike many top-tier models locked behind proprietary APIs and pricing, Mistral Large 4 offers transparency and control, allowing users to hold and fine-tune the model themselves. It is a mixture of experts model, meaning only a subset of its parameters activate per token, making it more efficient despite its massive size. The model supports a context window of 1 million tokens, processes both text and images, and includes advanced features like multiple reasoning modes and native function calling with strict schema enforcement.
Performance-wise, Mistral Large 4 shows significant improvements over its preview version, scoring 41% on the Terminal Bench benchmark, up from 28%, and demonstrating strong results on various coding and cybersecurity benchmarks. It reportedly leads among Western open-weight models in several areas, including finance and cybersecurity tasks, with high refusal rates for malicious requests. However, these results are primarily vendor-reported or from third-party benchmarks, so users are advised to verify performance against their specific workloads before adopting it in production.
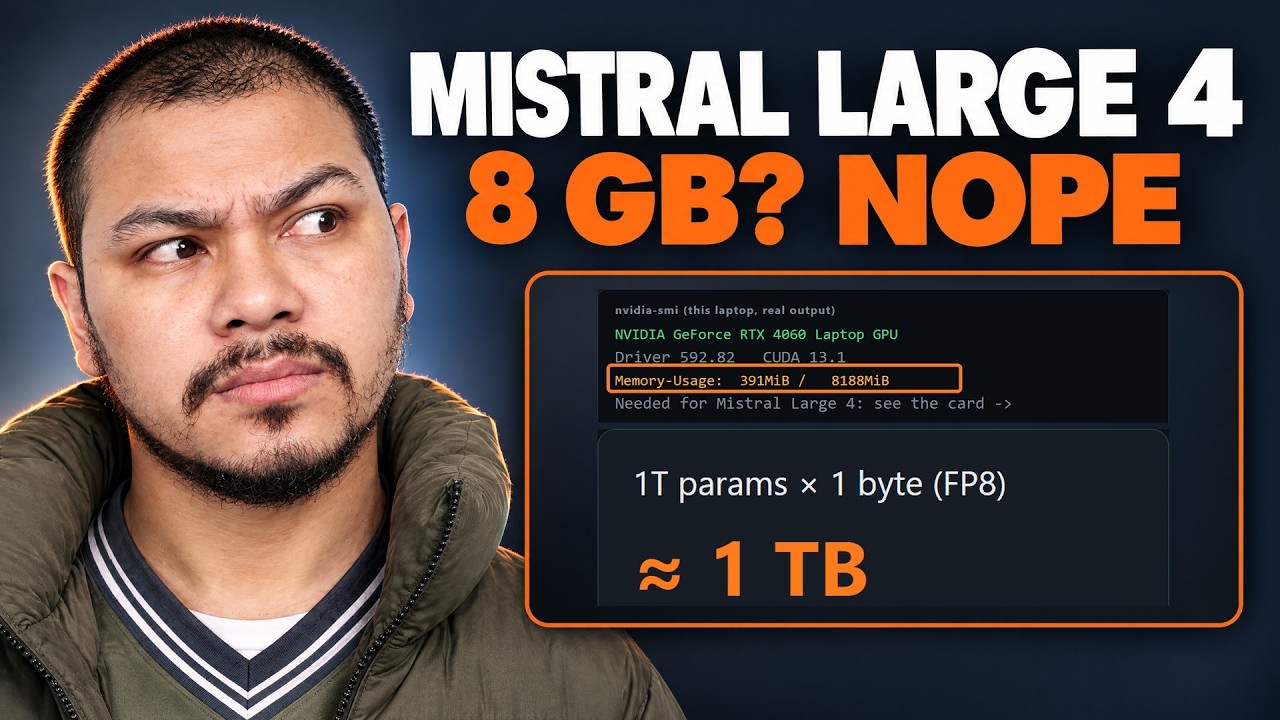
Despite its impressive capabilities, running Mistral Large 4 locally is currently impractical for most due to its enormous hardware requirements. The model’s checkpoint size is estimated to be around a terabyte, and it demands multiple high-end GPUs with substantial VRAM, far beyond typical consumer-grade hardware like an RTX 4060 or even an 80 GB GPU. Hosting options exist through Nvidia and other platforms, but self-hosting requires significant infrastructure. The model is designed for data center environments, and while there are tools for fine-tuning and customization, casual users will likely rely on hosted APIs.
Mistral Large 4’s open weights and licensing under a modified MIT license make it attractive for organizations prioritizing data privacy and control, such as banks, hospitals, and governments, especially in Europe where data sovereignty is a concern. The model’s openness also encourages research, auditing, and community-driven improvements, which could accelerate progress in open-weight models and narrow the gap with closed-source alternatives. Pricing for API usage is currently high but reflects the model’s scale and capabilities, with costs scaling with token usage and context window size.
In summary, Mistral Large 4 represents a major step forward in open-weight large language models, combining massive scale, advanced features, and openness. While it is not yet accessible for typical consumer hardware, its availability enables fine-tuning, self-hosting, and independent auditing, which are valuable for enterprises and researchers. The rapid improvements seen between preview and release suggest that open models are catching up quickly to proprietary ones, promising more affordable and flexible AI solutions in the near future.
Useful Links