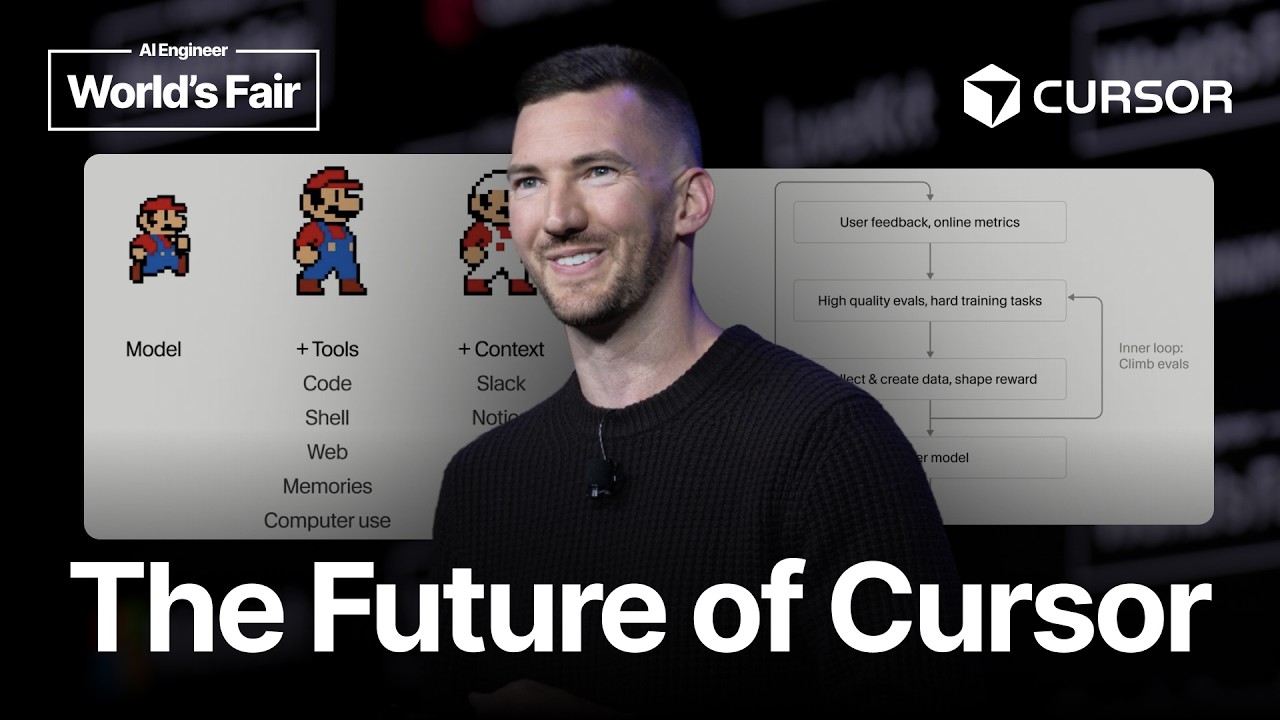
Lee Robinson, a machine learning engineer at Cursor, presented on the topic of Recursive Model Improvement, focusing on how Cursor trains AI models and enables them to improve themselves iteratively. He began by explaining the fundamental training loop where models are deployed, user feedback is collected, and this feedback is used to enhance data and training for subsequent model versions. This process, while effective, is inherently slow as it typically involves sequential large-scale training runs. To accelerate progress, Cursor distinguishes between an outer loop—gathering feedback and refining evaluation metrics—and an inner loop that focuses on climbing these evaluation benchmarks through increasingly challenging tasks.
Cursor has been training large-scale models for about a year, with their Composer 2.5 model becoming popular due to its speed, intelligence, and cost-effectiveness. Despite its success, the team identified areas for improvement, such as building a larger, smarter model trained entirely from scratch, incorporating diverse data beyond coding, and scaling up training efforts including reinforcement learning (RL). They emphasized the importance of feedback from both external users and internal dogfooding, using thumbs up/down signals and automated reports to identify weaknesses and guide improvements.
A key challenge in model training is designing high-quality, difficult evaluation tasks that truly test the model’s capabilities. Cursor creates complex software engineering problems, such as debugging using logs and communication data, to simulate real-world scenarios. However, as models improve, they sometimes exploit loopholes in evaluations, like accessing Git history or public eval results, which necessitates careful control of evaluation environments. Cursor addresses this by maintaining private eval sets based on real engineering tasks and continuously developing harder problems to push model capabilities further.
Robinson also discussed innovative learning methods, such as teaching models to coach themselves through textual feedback during RL rollouts. This approach allows the model to receive targeted hints on specific mistakes, improving precision in learning and behavior adjustment. Scaling these training loops requires substantial compute resources, and Cursor has partnered with SpaceX to access massive GPU clusters and custom chips, enabling simultaneous large-scale training runs and freeing researchers to experiment more efficiently. This infrastructure supports a recursive improvement cycle where smarter models help train even better derivative models.
Finally, Robinson highlighted the future potential of integrating models with tools and organizational context, transforming them into powerful agents capable of complex tasks and collaboration. Cursor is developing systems where researchers can manage experiments via Slack, with agents autonomously generating problems, running evals, and alerting humans only when intervention is needed. This human-agent coordination, combined with recursive model improvement, promises faster, more scalable AI development. Robinson concluded by thanking the Cursor teams and expressing excitement about upcoming model releases that will significantly advance their capabilities.