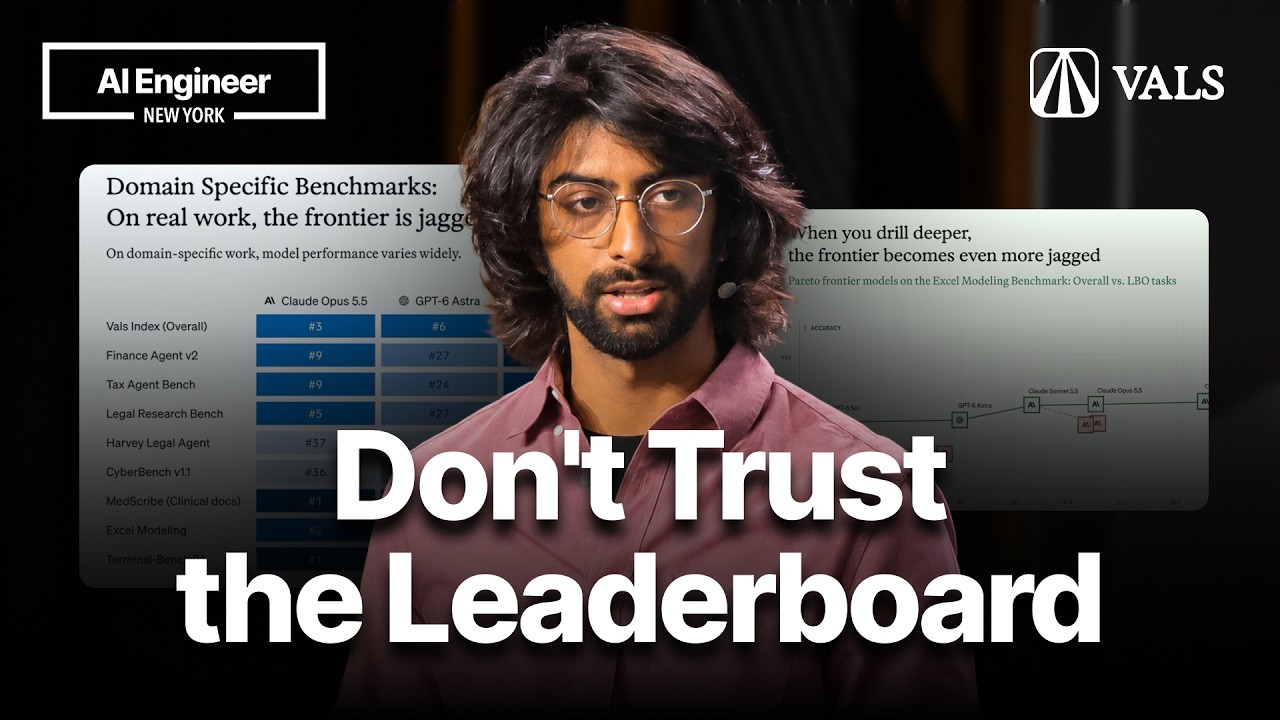
Rayan Krishnan from Vals AI discusses the limitations of traditional model cards and benchmarks in evaluating AI models, especially in specialized domains like finance. While model cards provide a high-level overview of a model’s capabilities through aggregated scores, they often mask the nuanced and inconsistent performance across different tasks and subdomains—a phenomenon he terms the “jagged frontier.” For example, in coding benchmarks, performance varies significantly across programming languages and libraries, and this fragmentation increases when considering factors like cost and latency. This complexity means that a single performance metric is insufficient for practical decision-making in enterprises.
Krishnan highlights the growing enterprise investment in AI, noting a doubling of AI spend year-over-year and widespread adoption, with 90% of organizations regularly using AI. However, only a small fraction (7%) have established clear ROI from these investments. A key insight is that organizations that actively track AI costs and spending are more likely to understand and realize ROI, whereas those that cannot quantify costs face barriers to broader AI adoption. He argues that rigorous evaluations (evals) tailored to specific tasks and cost-performance trade-offs are essential for unlocking AI’s value in practice.
A striking example from the talk illustrates how cheaper models on paper can end up costing more in practice due to inefficiencies like generating more tokens to complete tasks, resulting in higher expenses and lower performance. This disconnect between lab-reported metrics and real-world usage underscores the need for more granular and context-specific evaluations. In finance, for instance, different subcategories of tasks such as LBO modeling show distinct performance-cost frontiers, meaning that the best model for one task may be suboptimal or overpriced for another. Thus, firms must focus on the specific tasks relevant to their workflows rather than relying on broad benchmarks.
Krishnan also shares lessons learned from building benchmarks, emphasizing the importance of choosing appropriate accuracy metrics, ensuring validity by reflecting real-world tasks, maintaining reliability through sufficient sample sizes, and designing discriminative tests that differentiate model capabilities. He warns against common pitfalls like reward hacking, where models exploit evaluation criteria without genuinely solving the underlying problem, and stresses the need for benchmarks that support multi-turn interactions, reflecting the iterative nature of real-world work. Infrastructure challenges for running large-scale, consistent evaluations are also noted as a significant hurdle.
Finally, Krishnan presents a case study from Vals AI’s internal efforts to optimize coding tasks using evals. By analyzing GitHub repositories and pull requests, they identified which models were cost-effective and capable, debunking assumptions that open-source models are always cheaper or better. This approach enabled a 90% reduction in token costs while maintaining output quality. He envisions expanding this methodology to other knowledge domains like legal and finance, leveraging historical organizational data as a foundation for tailored evaluations. Ultimately, he argues that evals can codify institutional knowledge, transforming it into a competitive advantage and facilitating more strategic and efficient AI adoption across enterprises.
Useful Links
- Val’s Index Benchmark — Directly discussed as a key benchmark revealing nuanced AI model performance beyond single aggregated scores.