The video explains how LoRA fine-tuning efficiently adapts large language models by updating only a low-rank subset of parameters, leveraging the concept of intrinsic dimension which shows many tasks can be learned by adjusting a small number of directions in parameter space. It highlights LoRA’s practical benefits over full fine-tuning and prompting, demonstrating through experiments that low-rank adaptations achieve comparable performance with significantly reduced computational cost.
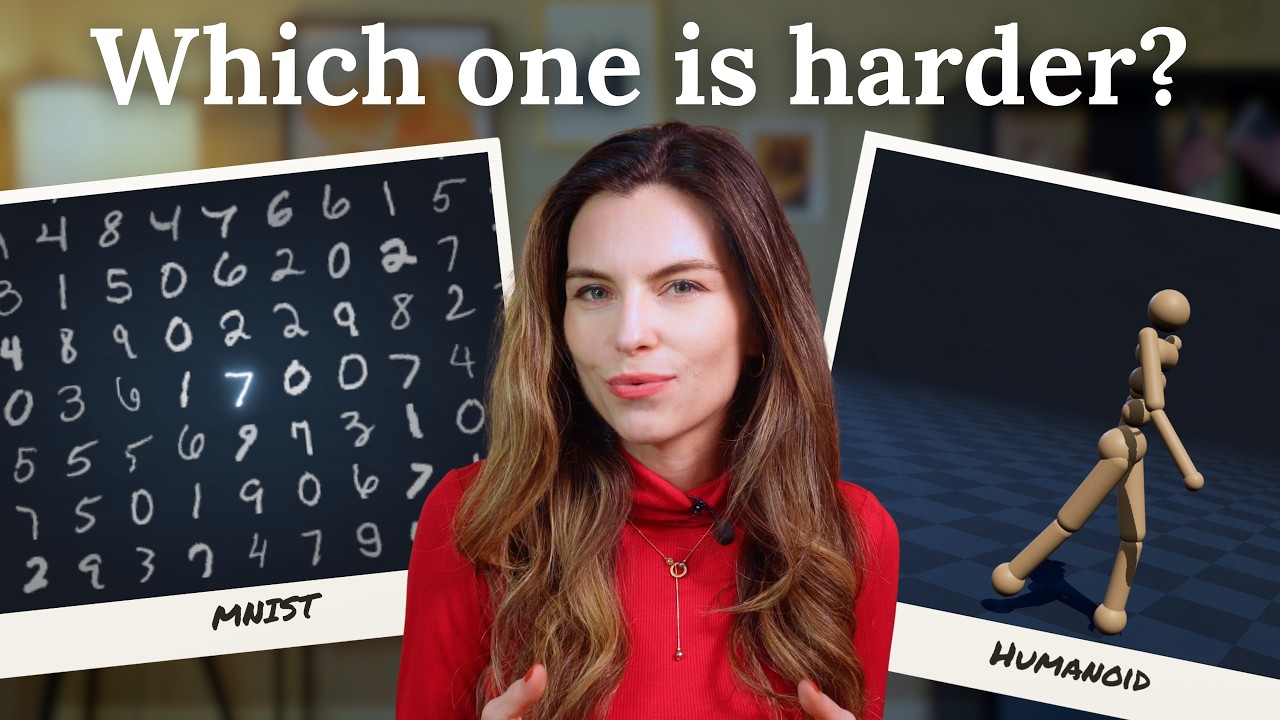
The video begins by comparing two tasks to illustrate the concept of task difficulty for neural networks: recognizing handwritten digits from small grayscale images and teaching a simulated humanoid robot with multiple joints to walk. Surprisingly, both tasks have similar intrinsic difficulty, measured by how many directions in parameter space a model needs to adjust to learn the task effectively. This concept of intrinsic dimension helps explain why LoRA (Low-Rank Adaptation), a popular fine-tuning method, is so efficient. LoRA fine-tunes large language models (LLMs) by training only a small subset of parameters, often less than 2%, making it computationally feasible to adapt massive models like Kimmy K3 with 2.8 trillion parameters.
The video then addresses the question of why fine-tuning is still necessary in the era of powerful LLMs that can perform many tasks via prompting. It highlights the limitations of prompt-based approaches, such as instability in scoring and the cost of repeatedly including examples in prompts (in-context learning). Fine-tuning, by contrast, involves training the model once on many examples, which is more reliable and cost-effective for certain applications like query routing. However, full fine-tuning is expensive because it updates every parameter in the model, requiring enormous computational resources and memory.
LoRA offers a solution by constraining the adaptation to a low-rank update of the model’s weight matrices. Instead of updating all parameters independently, LoRA represents the update as a product of two smaller matrices, drastically reducing the number of trainable parameters. This low-rank constraint limits the search space for fine-tuning but still allows the model to adapt effectively. The video explains the geometric intuition behind this: LoRA restricts the model’s parameter updates to a subspace spanned by a few learned directions, which is sufficient for many tasks due to the structure of the loss landscape.
The concept of intrinsic dimension is explored further through experiments that measure how many random directions are needed to achieve near-full performance on various tasks. Surprisingly, tasks like digit recognition and humanoid walking have relatively low intrinsic dimensions, meaning they can be learned by adjusting parameters along a small number of directions. This insight extends to large pre-trained models, where fine-tuning can be effectively done by learning a small number of directions, as demonstrated by experiments on models like RoBERTa. This empirical evidence supports the effectiveness of LoRA’s low-rank adaptation approach.
Finally, the video presents a practical fine-tuning experiment using LoRA on a 3.8 billion parameter model for a query routing task. The results show that even with a very low rank (R=1), the model achieves accuracy comparable to higher ranks (R=16), indicating that many directions in the adaptation matrix are redundant. Analysis using stable rank confirms that the effective rank of the adaptation is much lower than the maximum allowed, reinforcing the idea that LoRA’s low-rank constraint is not only efficient but also sufficient for fine-tuning large models. The video concludes by encouraging viewers to explore the topic further with provided resources.